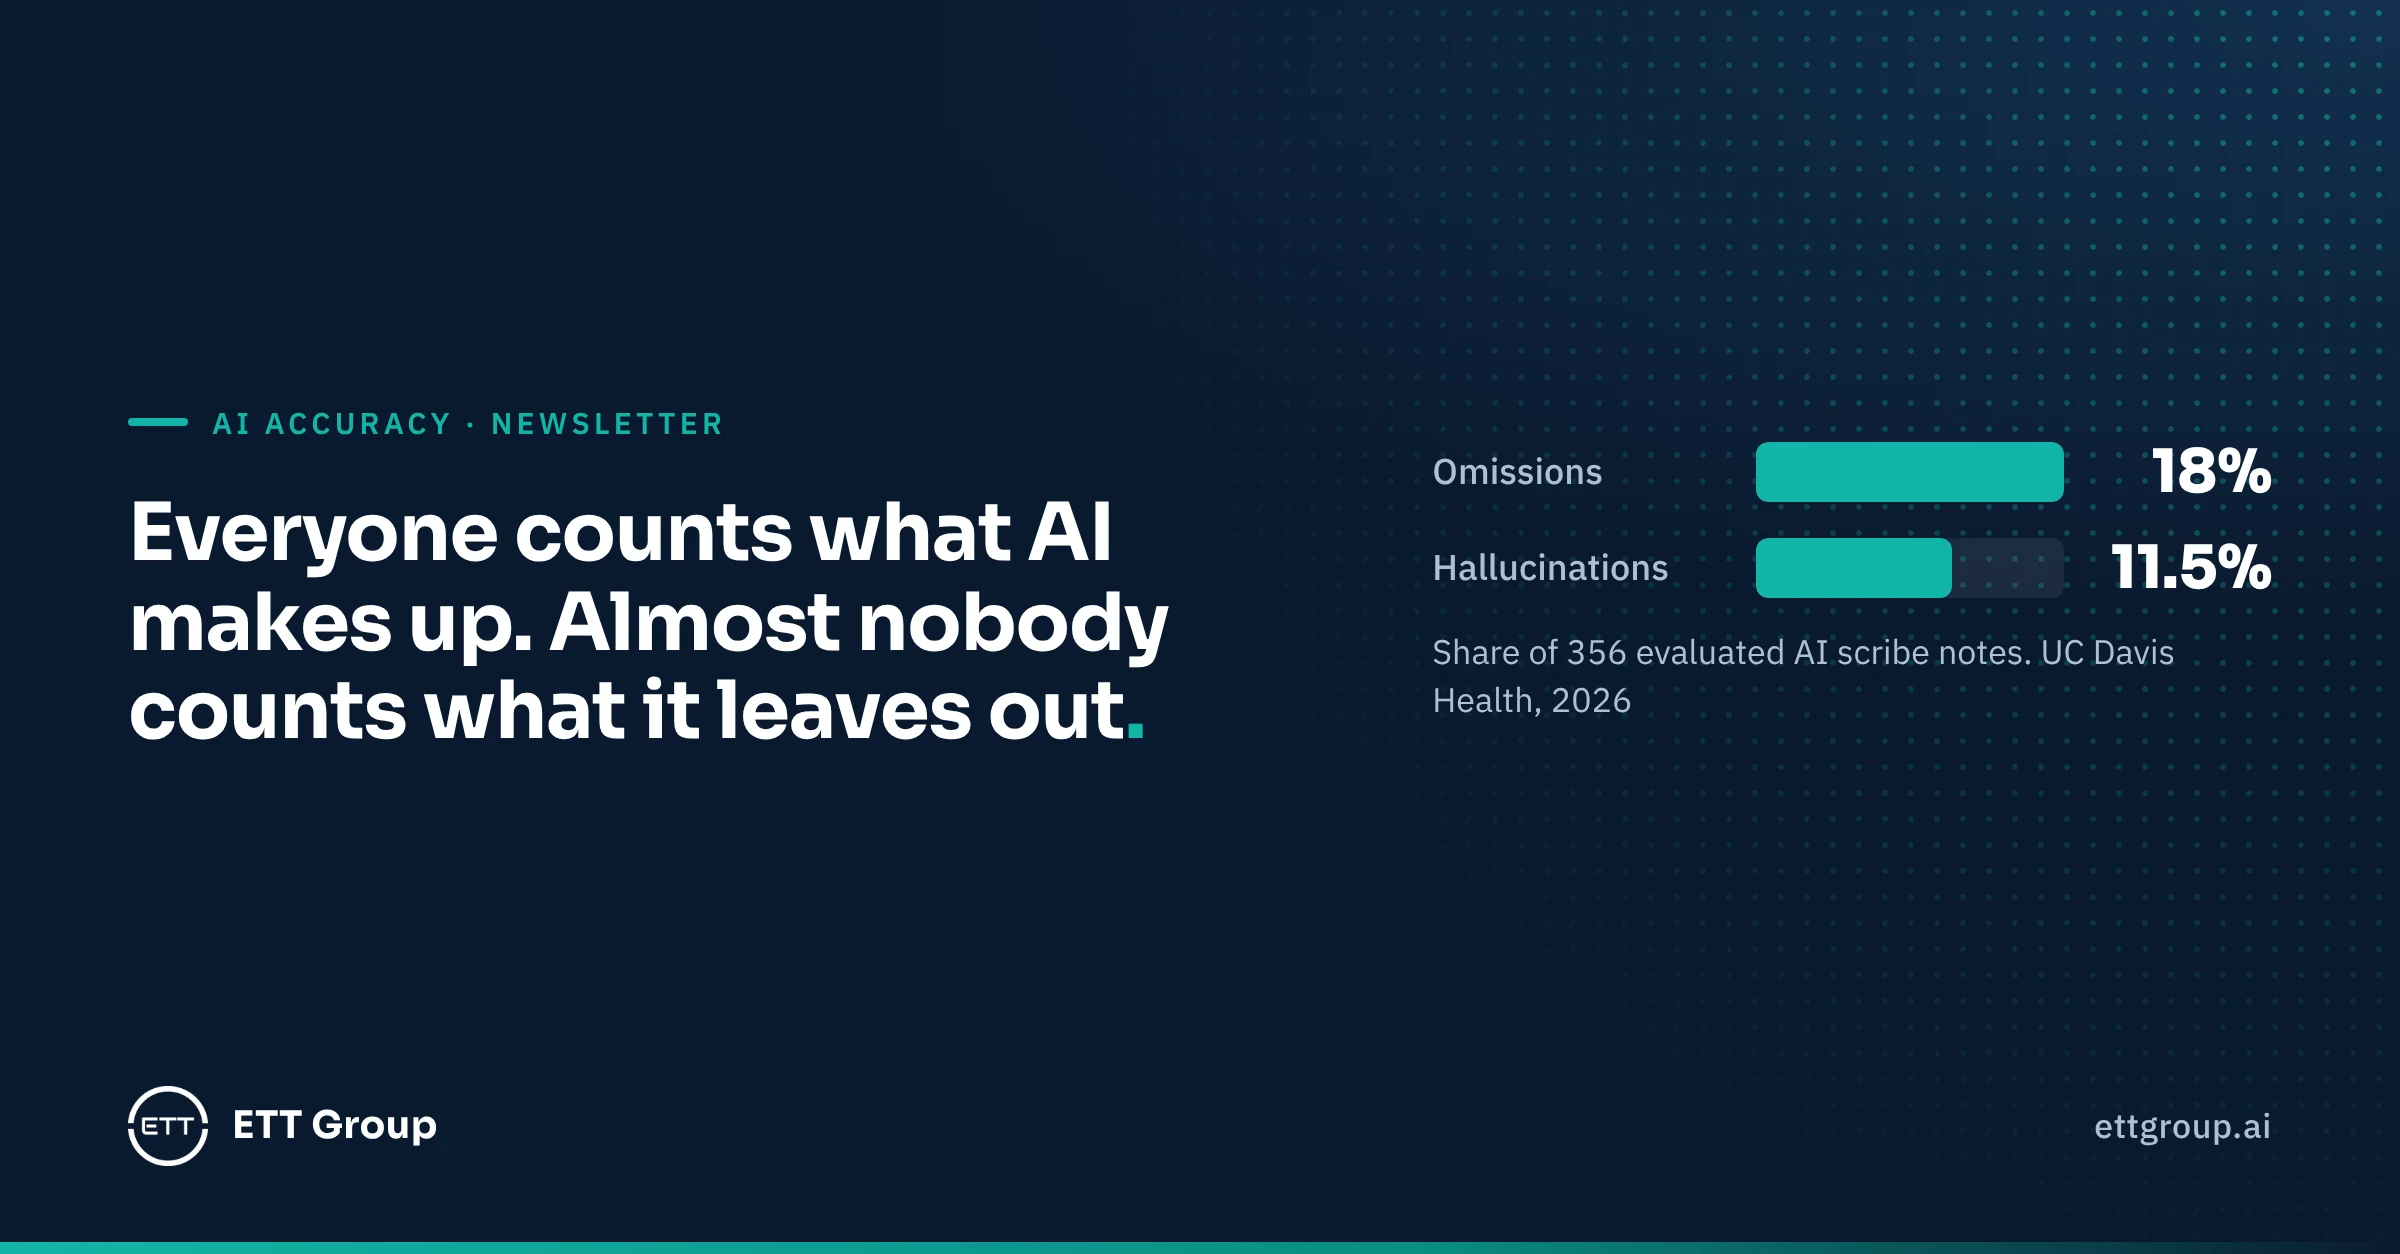
In one study of clinical notes, AI left things out more often than it made things up. Why omissions need their own number, and how to count them.
There's no shortage of talk in AI governance circles about AI accuracy: how to test it, how to evidence it, what to say when a regulator asks.
Most of that talk is about hallucinations. The invented citation. The made-up statistic. The confident answer with nothing behind it.
That's fair. Hallucinations are real and they're easy to picture. But the industry has got very good at counting one kind of failure and has mostly stopped looking at the other.
The other failure is what the AI left out.
The quieter failure
Picture three summaries. Every sentence in each of them is true to its source.
The first is a discharge summary. It gets the diagnosis, the medicines and the follow-up right. It doesn't mention the penicillin allergy.
The second summarises an insurance policy for a claims handler. It lists the cover correctly. It drops the exclusion clause.
The third summarises a court order for a client. It gets the outcome right. It misses the deadline to respond.
Those are illustrations, not real cases. But each of them would pass a hallucination check, because nothing in them is made up. Each of them could still do real damage, because the reader trusts the summary and never goes back to the source.
This is measurable, and it's not rare
Researchers have started counting omissions. A UC Davis Health study published in April looked at 356 AI scribe notes evaluated by physicians. Accidental omissions turned up in 18% of them. Hallucinations turned up in 11.5%. And 5.3% of the notes carried an error rated as a serious or imminent risk.
So in that study, the AI leaving something out was more common than the AI making something up. Yet when people quote an AI accuracy figure, it's almost always a hallucination rate.
Why the usual checks can't see it
There are two reasons omissions slip through.
The first is what gets measured in public. Vectara's hallucination leaderboard, one of the most quoted, scores how often a model's summary says something the source doesn't support. It measures unsupported additions. It doesn't measure what was dropped.
The second is how checking works. Most accuracy checks, including good ones, start from the output. Split the summary into claims, then check each claim against the source. That's the right way to catch fabrication. But a fact that isn't in the summary produces no claim, so there's nothing to check and nothing to fail.
That leads somewhere uncomfortable. The shortest summary can look like the most "accurate" one. Say less, get less wrong. If accuracy is your only sign-off measure, you are quietly rewarding summaries that leave things out.
It's why we put this line on our Accuracy Evidence File: "No contradictions found" is not a statement that the output is true.
The review standard changes the answer
There's a second problem, and it matters to anyone who has to report a number to a board or a regulator.
A preprint published in August, "One note in three", audited 565 notes from three commercial ambient scribes in UK primary care and the US. Depending on the review standard applied, between 28% and 97% of the notes carried a failure.
Same notes, same scribes. The answer ran from just over a quarter to almost all of them, depending on how strict the review was.
I don't say that to knock the study. Reporting the range was the honest thing to do, and it's the most useful finding in the paper. If you don't decide what counts as a failure before you check, the number you get tells you more about your reviewer than about the AI.
Some people already ask for this
For the NHS in England this isn't theory. NHS England's guidance on ambient scribing says adopting organisations should get users, such as clinicians, to validate the rate of errors and omissions, and should collect monitoring data independently of the manufacturer.
Errors and omissions. Two things, named separately. That's the right instinct, and I'd apply it well beyond healthcare.
If you work to the EU AI Act, Article 15 will ask providers of high-risk systems to declare accuracy metrics in the instructions for use. For Annex III systems that now applies from 2 December 2027. When you choose those metrics, make sure one of them counts what's missing.
What I'd do instead
Four rules. None of them needs new technology.
- Decide what must be present before you check. For each type of document, write a short list of facts a summary may never drop: allergies and medicines in a clinical note, exclusions and limits in a policy, deadlines and conditions in an order. Have it signed off by someone who does the work.
- Pull those facts from the source without looking at the summary, then mark each one present, changed or missing.
- Report omissions as their own number. Never average them into an accuracy score. An average is where omissions go to hide.
- State the review standard you used, and put every disagreement in front of a named person who records the decision.
I've written the full method up as a guide, with a table template you can copy: How to measure what an AI summary leaves out.
Try one question on every accuracy claim you hear: what did it leave out, and who counted?
And closer to home: when your organisation signs off an AI summary, does anyone check what's missing, or only what's there?
Sources
- UC Davis Health, JMIR Medical Informatics, Apr 2026
- Fox et al., "One note in three", preprint, Aug 2026
- Vectara hallucination leaderboard
- NHS England, ambient scribing guidance
- EU AI Act, Article 15
- EU AI Act implementation timeline
This is a business view, not legal advice.